There is a specific kind of hubris that builds up when your homelab runs smoothly for almost a year. You start trusting your own setup. You start thinking your architecture is actually solid. Then you get a week like this one, where the infrastructure decides to humble you with three completely unrelated failures, one right after the other.
The 15GB Log File
It started with a notification: the production server was at 95% storage capacity. This was weird. It hadn’t even been a week since I purged and cleaned the server. I don’t have a lot of system storage, so I only give the production server (which holds all the services I use regularly) 64GB. I could write a cron job to clean and purge the system automatically after service updates, but since I use Docker, the biggest storage eaters are old images, and I prefer to manage those manually for now.
After some investigation, I found the culprit. It was a log file. Specifically, a 15GB Traefik log file.
It was just my turn to make this mistake. I had left the DEBUG flag on while troubleshooting another bug and never switched it back to INFO. If it had been any other time, it would have taken much longer to reach that size, but this week I was doing something that required a lot of traffic. I know a 15GB file isn’t the 400GB log file horror story you sometimes read about, but bear in mind that Traefik only gates the production server and a few external services, not the whole lab. The prod server runs about twenty services, and I am the only user.
The Expired Key
The second thing that happened was a Tailscale key expiring.
I didn’t notice right away. I had set up a job to run and notify me when it finished, and I stepped out for a coffee. The job was supposed to take 15 minutes. After 30 minutes with no notification, I checked my devices on Tailscale. I could only see the phone I was holding.
Previously, I had shut down all the VMs and LXCs that weren’t in use, including the subnet router LXC. If everything was working correctly, I should have seen two nodes: my phone and the prod server. I couldn’t think of a cause. A power outage again? I panicked. Not because the server is running something critical it wasn’t a dire situation but just on principle. In the end, I’m just cosplaying as a SysAdmin. (By the way, the coffee tasted weird that day.)
When I got home and my phone connected to the LAN, all the notifications I was waiting for suddenly flooded in. Everything seemed to be working exactly as it should. After some digging, I found out the Tailscale key for the production server had expired three days ago. I hadn’t noticed because I was on the LAN the whole time a nice way of saying I hadn’t left the house in at least three days.
If I had the subnet router LXC running, I would have seen it in the Tailscale devices and been able to access my system. But it was down. I had done a full system upgrade that day, including that LXC, but it threw a dependency error, so I put it off for later. Just like the log file, it was my turn to experience something your system depends on quietly expiring.
The Hard Freeze
The big one: a complete system freeze.
I was working on something quite important on the server when I suddenly lost total connectivity. I was confused because I could see the machine was physically on. The monitor connected to the server was displaying my dashboard, so it wasn’t a power outage. I tried accessing my services, but I couldn’t reach anything, not even the Proxmox UI.
I went over to the machine to access the terminal and figure out what was happening. The problem is that the monitor shows a dashboard, I use a kiosk in an LXC for that by hijacking stdout (I have a draft for a post about this, but I’m not sure if I’ll publish it). I set it up in a way that I can always regain access to the TTY by shutting the LXC down, but that’s not exactly straightforward when nothing else is working correctly.
The system was simply frozen. I couldn’t do anything except hard reset the server. After the reset, pretty much everything worked exactly as designed.
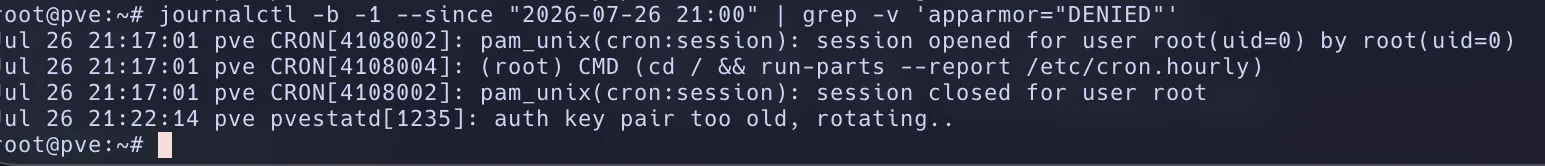
I got straight to work investigating the cause. All the logs showed the same thing: a hard freeze at the exact same time.
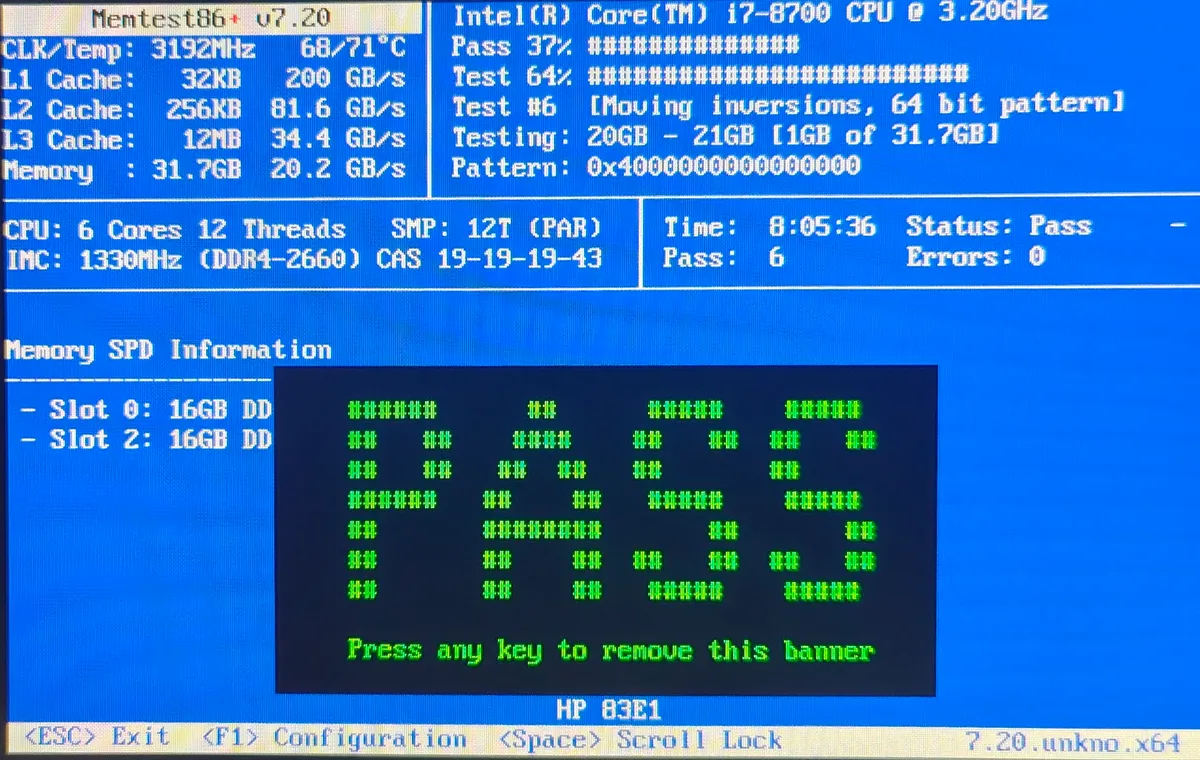
I had a few hypotheses, but my biggest fear was bad memory. RAM is expensive right now, and I wouldn’t be able to replace it. I ran a memtest for the entire night. It passed.
My current hypothesis is micro-sags caused by dirty power. We always have dirty power, but lately, it’s been terrible, with frequent power outages. And before you ask why I’m not using a UPS to fix it: I just can’t afford one.